FADU’s FS-SSD Moves File Handling Into the Drive to Cut Host CPU Work
FADU’s FS-SSD handles file operations inside an SSD, with early tests showing steady NFS throughput as server cores fall. Hardware validation is still ahead.
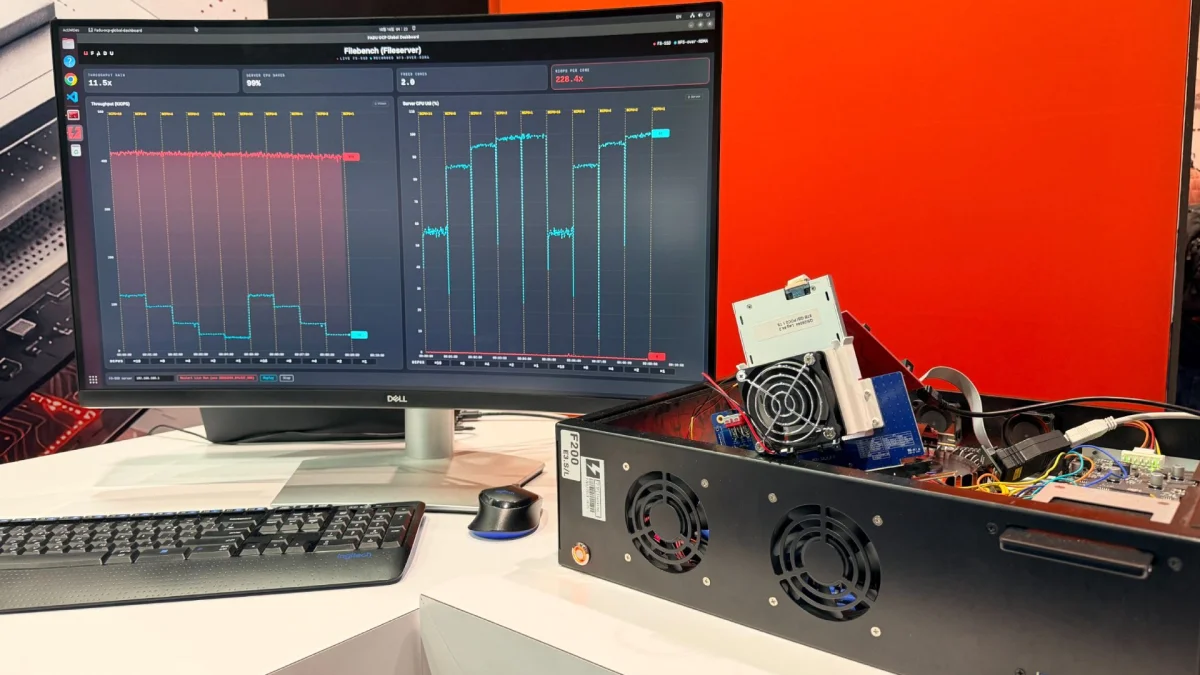
FADU’s File-Semantic SSD (FS-SSD) puts file-system operations inside the SSD, aiming to let GPUs, DPUs and network cards access files without routing requests through a host file system, block layer or storage-server CPU. The approach targets a part of storage that accelerators haven’t eliminated: the control path that locates files, checks access and maps file data to flash.
The Seoul-based SSD controller designer presented FS-SSD at the 2026 OCP Global Summit. Its white paper describes a design that carries NFSv3 operations inside standard NVMe commands. FADU says it expects partner samples in Q3 2027. The technology remains under development, and several of its most striking figures come from preliminary testing rather than finished hardware.
File operations move into the SSD
Accelerators can move data without asking a CPU to copy each byte, but conventional storage stacks still use host processors to handle file-system and block-layer work. FADU estimates those layers consume about 30% of CPU cycles in a GPUDirect Storage random-read workload. Existing ways to bypass the host can remove that overhead, but they also give up file-level access. FS-SSD is designed to retain files while reducing the CPU work needed to reach them.
FADU chose NFSv3 because it has 21 operations, is stateless and works independently of a particular operating system or file system. In the company’s design, the drive handles path lookup, access checks and the mapping between files and flash addresses. The current implementation supports PCIe. FADU says it can also work over NVMe-oF using RDMA or TCP, without requiring a new transport.
Inside the drive, FADU combines the file system with the flash translation layer and a file layer derived from F2FS. File-system nodes and data blocks align with flash pages, while sections align with erase units. The resulting F2FS node table acts as a “File Map,” connecting node IDs to physical flash addresses.
This arrangement changes how the SSD uses its DRAM. A standard SSD typically uses most of its mapping memory to track logical addresses. FADU says FS-SSD uses about the same DRAM capacity—roughly 0.1% of NAND capacity, or about 1 GB per terabyte—but can allocate around 95% of it to a cache of frequently used file-system nodes.
It also combines cleanup work that would otherwise happen in both the host file system and the drive. FADU calls the interaction between those two garbage collectors “double GC,” because their cleanup can amplify writes. In a mixed sequential and random workload on a research prototype, the company reports 63% lower write amplification than host F2FS. That result came from synthetic fio workloads running on NVMeVirt, an SSD emulator from Seoul National University, so it hasn’t yet been demonstrated on the target hardware.
Early results and their limits
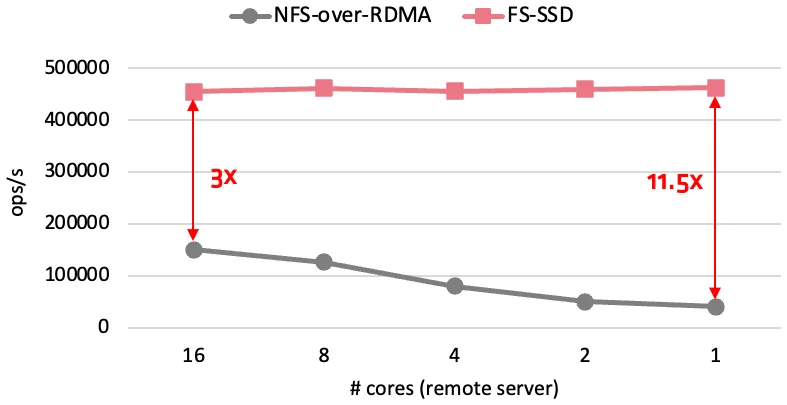
FADU’s preliminary NFS test used a drive based on its FC6161 Gen6 controller in a PCIe 5.0 host. As the server configuration fell from 16 cores to one, the company reports that remote file throughput stayed near 460,000 operations per second. In the same comparison, Linux NFS over RDMA delivered about 150,000 operations per second with 16 cores and 40,000 with one.
The Filebench test used a metadata-heavy file-server workload: 10,000 files arranged in a multi-level tree, an average directory width of 20, average file size of 128 KB and 50 client threads. FADU also ran fio tests with an Intel Core i5-13600K client and server, 128 GB of DDR5 and a Mellanox ConnectX-6 100 Gbps network card. Sequential tests used one thread, a queue depth of 128 and 128 KB blocks; random tests used four threads, the same queue depth and 4 KB blocks.
| Setup | Sequential read (MB/s) | Sequential write (MB/s) | 4 KB random read (MB/s) | 4 KB random write (MB/s) |
|---|---|---|---|---|
| F2FS | 14,120 | 4,510 | 7,850 | 3,980 |
| Ext4 | 14,130 | 7,050 | 9,120 | 4,560 |
| FS-SSD, kernel client | 14,140 | 11,940 | 8,070 | 4,320 |
| FS-SSD, SPDK client | Not reported | Not reported | 13,000 | 7,030 |
| Raw block, SPDK | Not reported | Not reported | 13,990 | 13,240 |
The SPDK results put FS-SSD at about 93% of raw-block performance for 4 KB random reads and 53% for random writes. The in-drive file layer therefore carries a larger cost on writes in this test. FADU’s kernel-client figures are also below Ext4 by 11.5% on random reads and 5.3% on random writes, according to the source’s calculations.
All sequential read results cluster around 14.1 GB/s, which is close to the link limit of the PCIe 5.0 host. The controller is Gen6, but these figures don’t show performance in a PCIe 6.0 system. And the one-core NFS comparison is a demonstration of a specific test configuration, not yet evidence of performance across a range of production servers.
Access, coordination and missing features
FS-SSD’s host-free path lets a GPU place NFS-over-NVMe commands in queues in its own memory, potentially including HBM. A remote DPU or SmartNIC can also submit commands to the drive. Data can then move from SSD to network card over PCIe peer-to-peer DMA and leave as RDMA writes. FADU lists GPU file reads and checkpoints, DPU-served web content and a just-a-bunch-of-flash (JBoF) file server as intended uses. GPU access is available today through GPUDirect Storage with the kernel client.
Shared access raises questions about write ordering and cache consistency. FADU says the current design has no cross-host locking because it doesn’t implement NFS’s lock manager. Each write is applied as a whole and in order; when writes overlap, the later one wins. Kernel-mounted clients can use advisory locks among themselves, while GPU and SPDK clients must coordinate in their applications. At larger scale, FADU says a pNFS metadata server can handle coordination.
Kernel clients use caching as they would with ordinary NFS. GPU and SPDK clients don’t cache data in this design. That keeps the path simpler, but applications using several types of client need to account for where coordination and caching happen.
Access checks also depend on identities carried in NVMe commands. FADU says it addresses the risk of a client faking user or group IDs with capability-based authentication: each command carries a capability from an external authentication server and a code generated with a key shared by that server and the drive. The company says Kerberos support is planned. Its published material doesn’t explain the capability mechanism in detail.
FADU describes the current release as missing access-control lists and other features, while drive encryption uses the FC6161’s standard TCG Opal support. For power loss, the design uses capacitors to flush metadata, buffered writes and a log of operations in progress. After restart, the drive replays unfinished operations; FADU says an acknowledged write is durable.
Roadmap and the next proof point
FADU’s longer-term plan is a JBoF system built from FS-SSDs, a PCIe switch and a DPU or network card that handles NVMe-oF in hardware. The company estimates this design could use about 42% less power and cost about 57% less per 16-drive server, with higher rack density and lower five-year total cost of ownership. Those are company projections, not results from a deployed system. FADU expects the drives to sit behind existing pNFS metadata servers.
The company’s roadmap calls for Gen6-host results by Q1 2027, including hardware write-amplification figures; partner samples in Q3 2027; and a hostless JBoF reference design using Xsight Labs E1 DPUs by the end of 2027. FADU also plans to start discussions on file-semantic commands at NVM Express and OCP Storage, though it hasn’t submitted a proposal. It says OEM and ODM discussions remain at an early stage.
The premise is clear: move file lookup and access handling closer to flash so accelerators can work with files while the host does less storage processing. The next useful evidence will be Gen6-host measurements, hardware write-amplification results and partner samples. Those tests will show whether the early throughput gains hold up beyond the emulator and PCIe 5.0 testbed—and how the design behaves when real applications share a drive.


